A research lab for speech AI
We’re researchers training speech AI to understand words and how they’re spoken. Our models use tone, rhythm, and emphasis to return transcripts with emotion and speaking-style labels. We publish our evaluations so you can inspect the results before building with them.
Backed by a16z speedrun.
The lab also supports the oruk organization, our nonprofit arm bringing speech technology to endangered languages.
The team
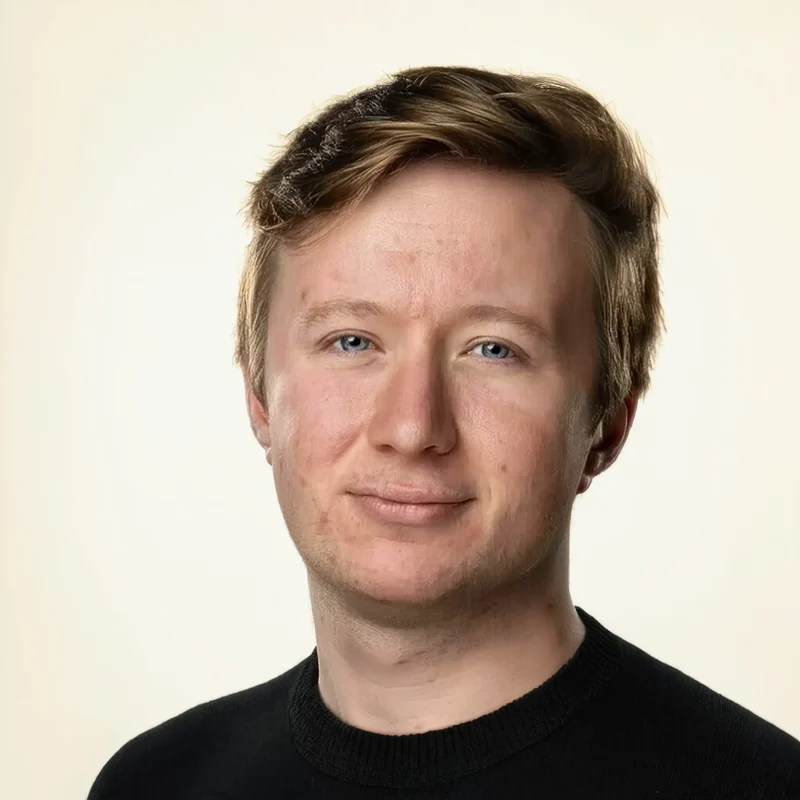
Daniel D'Angelo
Speech Data Specialist
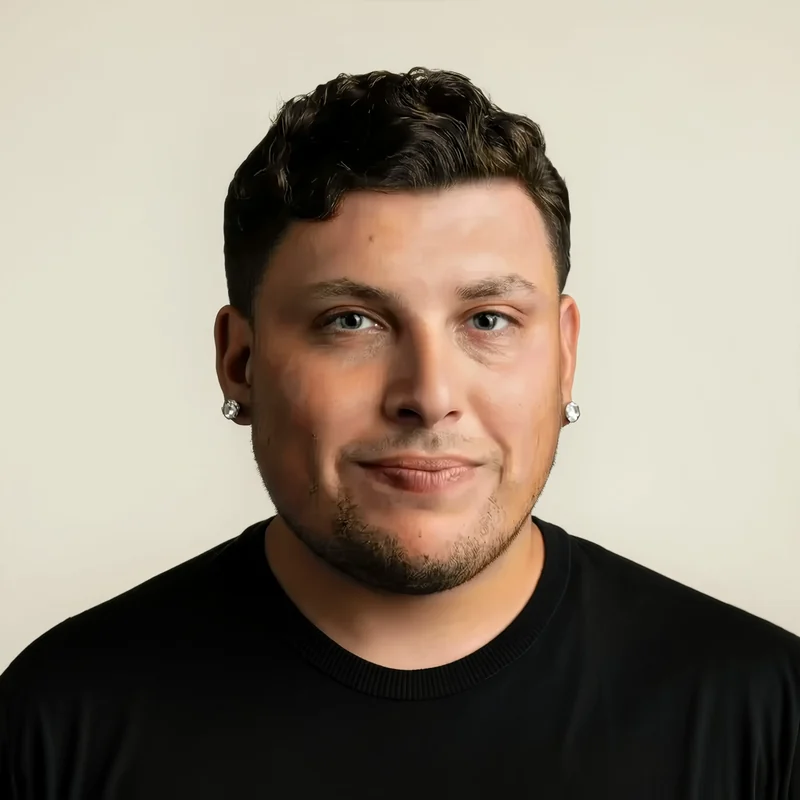
Anders Hedberg
Speech Data Specialist
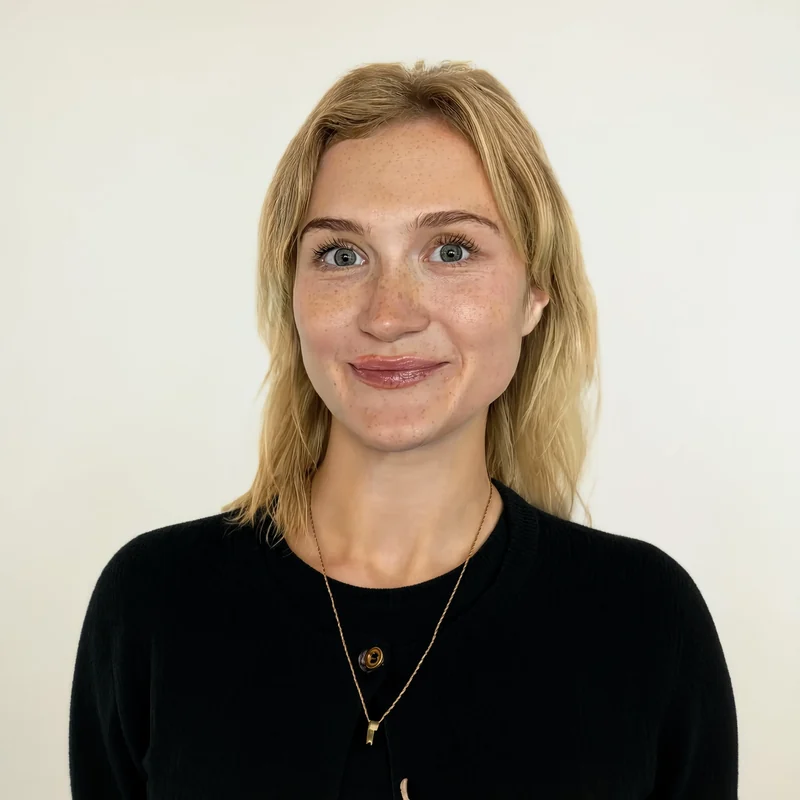
Anastasia Zaporozhtseva
Speech Data Specialist
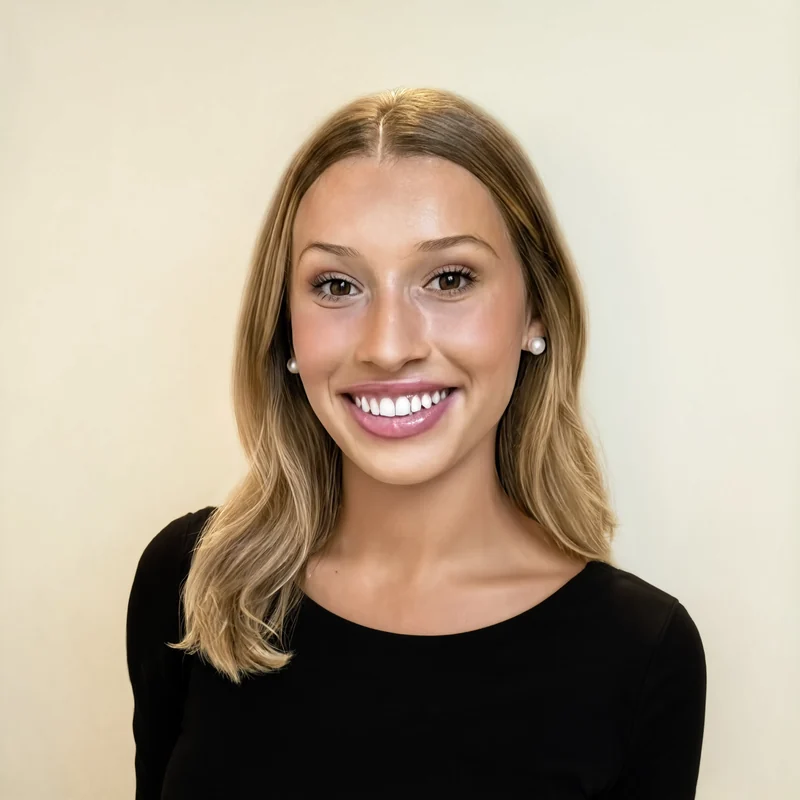
Natalie Love
Speech Data Specialist





Advisors


Words and delivery
We model transcription, emotion, and speaking style together, so applications can work with what was said and how it sounded.
Published evaluations
We publish evaluation methods, comparison results, and limitations so researchers and developers can inspect our work.
From research to your product
Use our models through one API, with SDKs, examples, and a playground for your own audio.